
Migrate from FastAPI to LitServe
LitServe builds on FastAPI, addressing the challenges of scaling machine learning models in production. While FastAPI excels at API development, LitServe automates tasks like batching, autoscaling, and resource management, making it easier to handle high request volumes and model scaling.
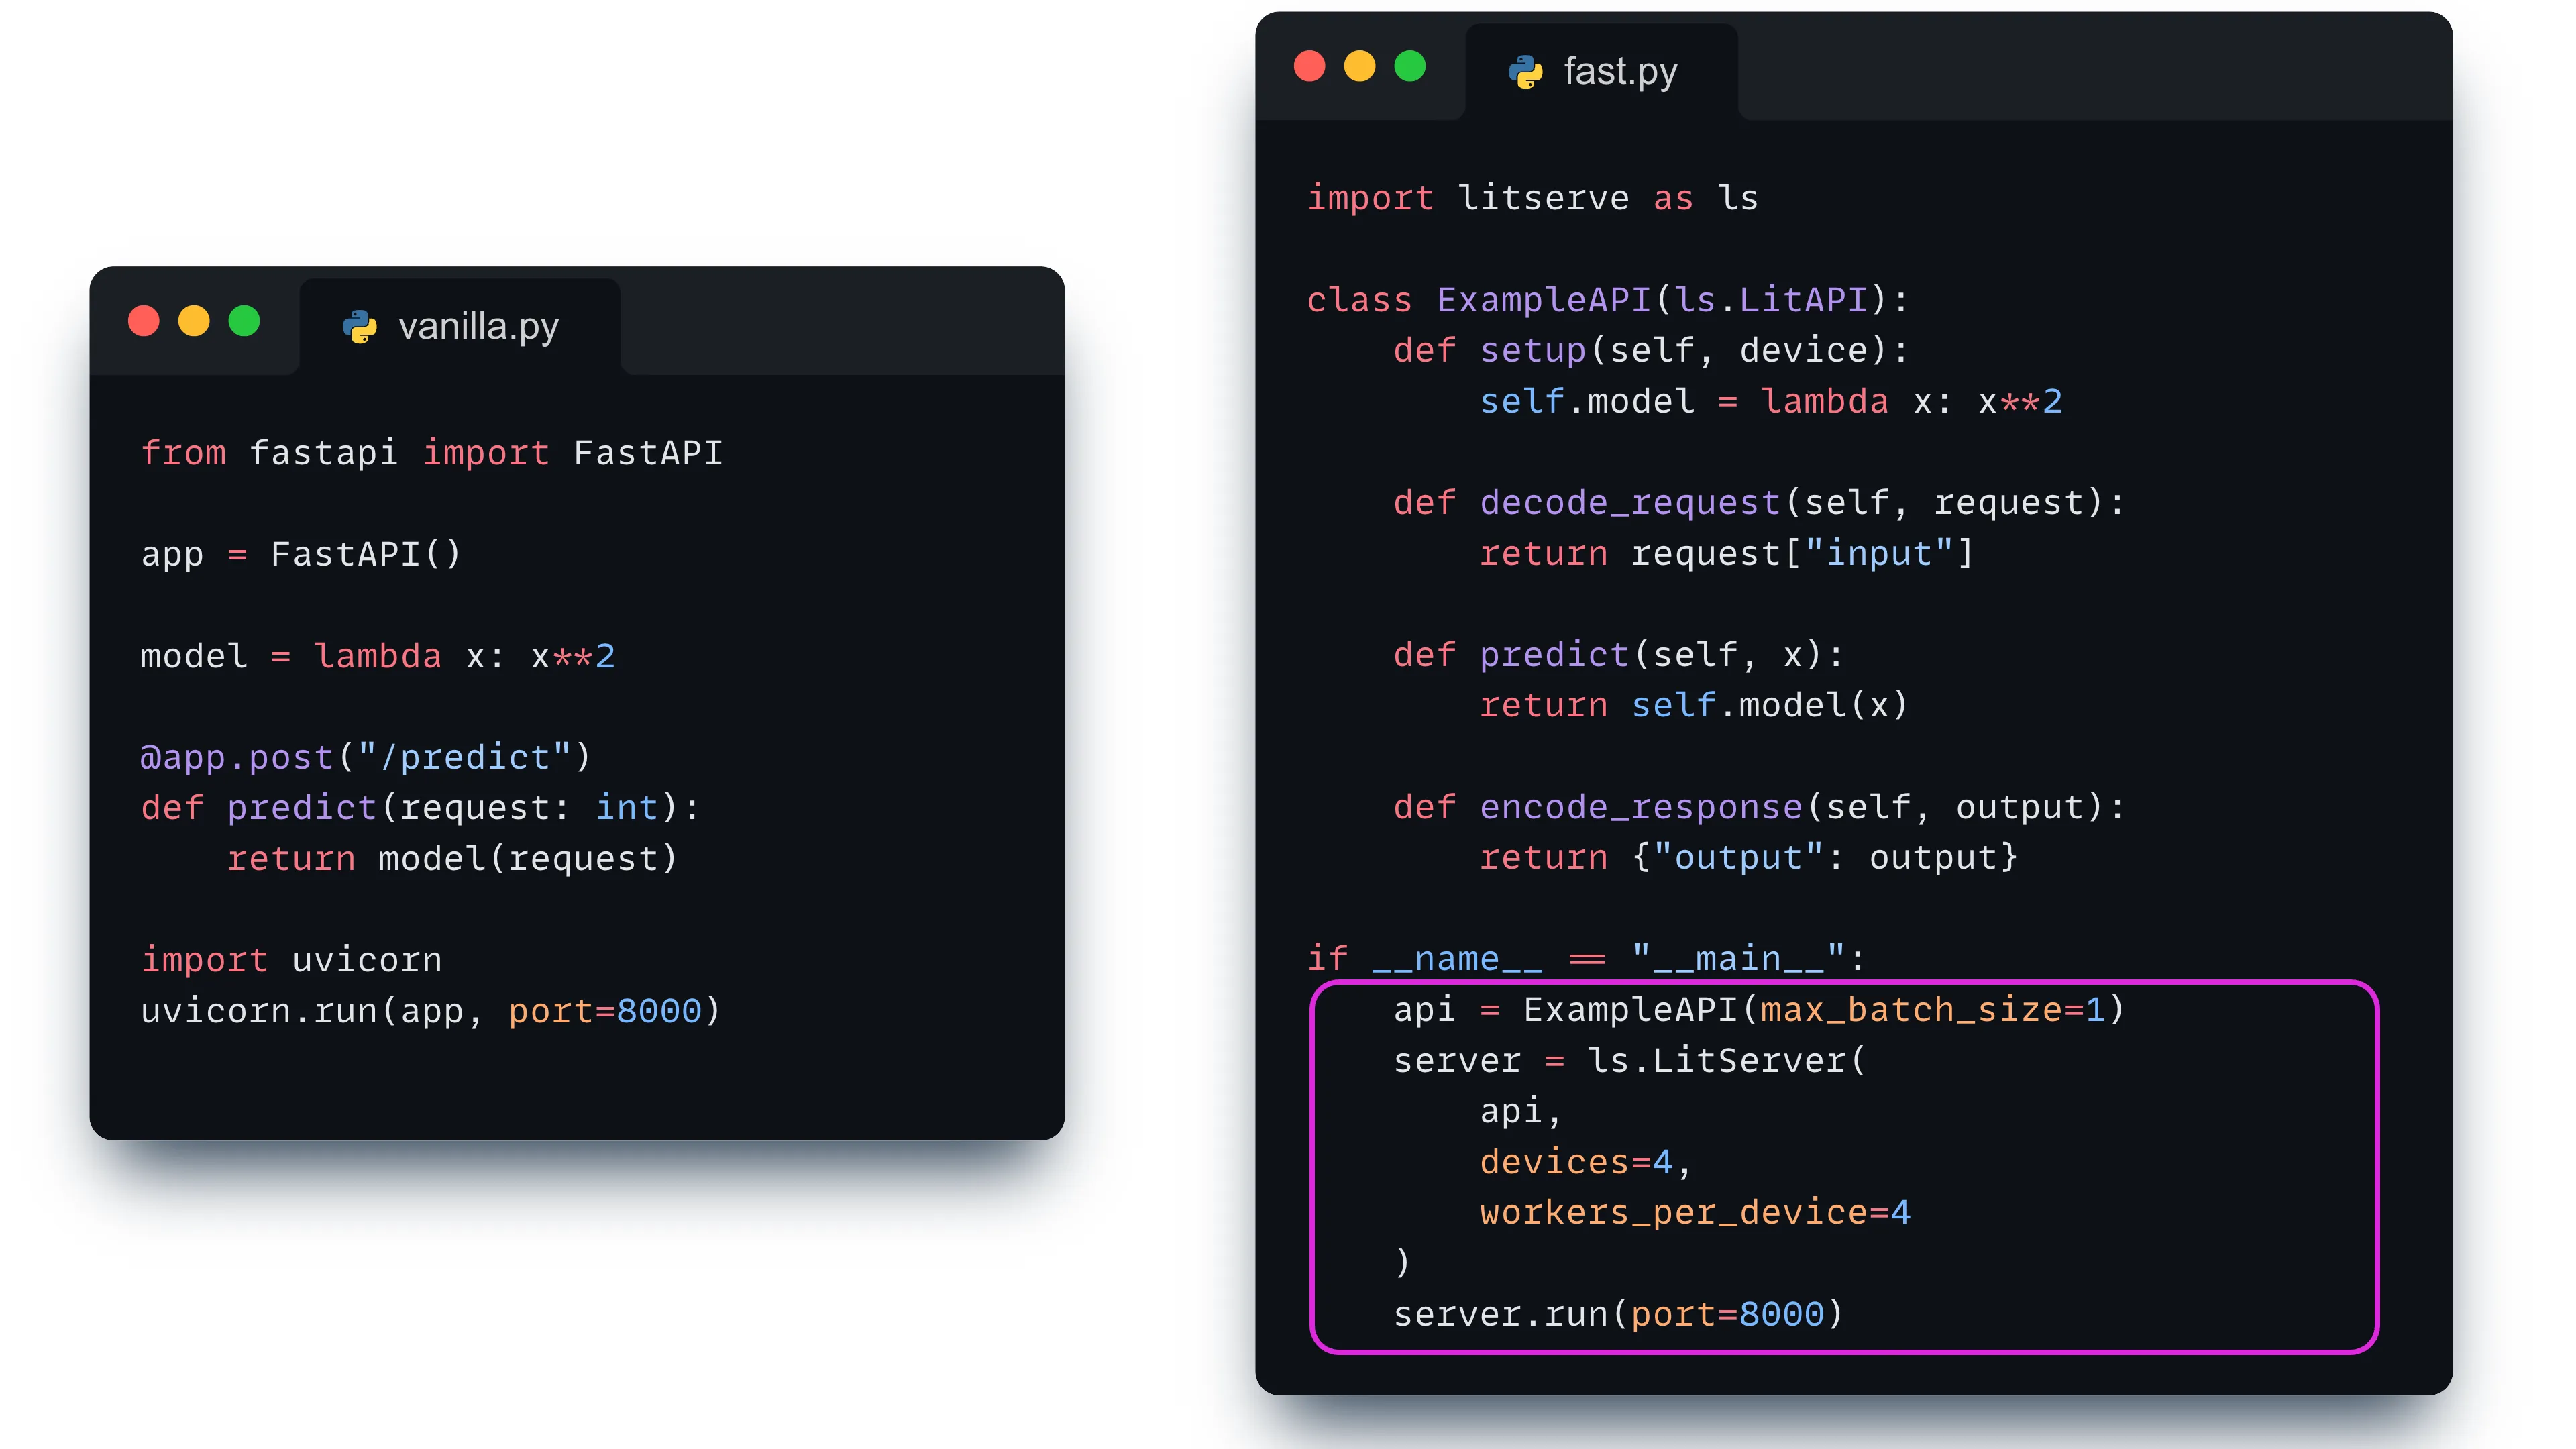
FastAPI vs LitServe
FastAPI is great for building APIs, but handling the scaling of AI models and managing high volumes of requests can get complicated. LitServe improves the process by automatically handling the following:
- Clear separation of concerns: Request lifecycle is separated into functions handling specific stage such as request decoding or model inference.
- Batching: LitServe automatically batches incoming requests to improve throughput.
- Autoscaling: LitServe scales across GPUs or available resources without any configuration overhead, ensuring optimal resource utilization under varying loads.
- Cloud deployment: Deploy model API with a single command to Lightning cloud.
- and much more...
LitServe handles these concerns automatically while preserving FastAPI compatibility. Endpoints keep working, middleware stays in place, and deployments require a single command.
Migrate from FastAPI
In this section, we will walk through the process of migrating a FastAPI inference endpoint to LitServe.
FastAPI
Let’s begin by serving a simple model that takes an integer input and returns its square.
from fastapi import FastAPI

app = FastAPI()

model = lambda x: x**2

@app.post("/predict")
def predict(request: int):
    return model(request)

import uvicorn
uvicorn.run(app, port=8000)
To test this API, we can use a simple client script to send a POST request:
import requests

response = requests.post("http://localhost:8000/predict", json={"input": 4})
print(response.json())  # → 16
LitServe
Now that we've seen how a basic FastAPI inference endpoint works, let's walk through the process of migrating this logic to LitServe.
In LitServe, the inference process is broken down into four primary methods:
- setup: Loads the model once at startup, typically on a specific device like a CPU or GPU.
- decode_request: Preprocesses incoming requests, such as converting input data or tokenizing text.
- predict: Runs inference on the processed input.
- encode_response: Formats the prediction result into the expected output format for the client.
import litserve as ls

class ExampleAPI(ls.LitAPI):
    def setup(self, device):
        self.model = lambda x: x**2

    def decode_request(self, request):
        return request["input"]

    def predict(self, x):
        return self.model(x)

    def encode_response(self, output):
        return {"output": output}

if __name__ == "__main__":
    api = ExampleAPI(max_batch_size=1)  # Defines the maximum batch size for inference
    server = ls.LitServer(
        api,
        devices=4,  # Number of devices (e.g., GPUs) to use
        workers_per_device=4  # Number of workers per device
    )
    server.run(port=8000)
Running the above script will start a LitServe server that handles batching, scaling, and other advanced features automatically. You can still interact with it the same way as you did with FastAPI:
import requests

response = requests.post("http://localhost:8000/predict", json={"input": 4})
print(response.json())  # → {"output": 16}
Mapping FastAPI to LitServe
In this section, we’ll compare how FastAPI concepts map to LitServe’s structure. Understanding these key differences will help you smoothly transition your FastAPI logic into LitServe’s more scalable and optimized framework.
- Routing: In FastAPI, routes are defined with decorators like
@app.post("/predict"). In LitServe, we define endpoints as methods in a class that inherits from LitAPI. - Request Handling: In FastAPI, we handle requests directly in route functions. In LitServe, requests are preprocessed in the
decode_requestmethod, which separates input handling from inference. - Model deployment: FastAPI requires manual scaling, typically by running multiple server instances. LitServe handles autoscaling and batching automatically.
| FastAPI concept | LitServe equivalent | Key benefit |
|---|---|---|
| @app.post route | decode_request / predict | Clear separation of parsing vs inference |
| Inline model load | setup method | Model loads once at startup with LitServe for each process. |
| Response | encode_response | Explicit response formatting |
| uvicorn.run(app) | LitServer(...).run() | Adds autoscaling, batching, GPU support |
Conclusion
Migrating from FastAPI to LitServe allows you to enhance your API with autoscaling, batching, and multi-GPU support while keeping your existing FastAPI routes intact. LitServe automates scaling and batch processing for AI models, which can drastically improve throughput and performance. After migration, explore advanced LitServe features such as continuous model updates, multi-cloud deployment, and real-time inference optimizations to fully harness its capabilities.
Was this page helpful?
Thanks for the feedback.